AI Evaluation & LLM Data
Structured human judgement on what AI systems produce, so you can measure quality, find failure cases, and improve with confidence.
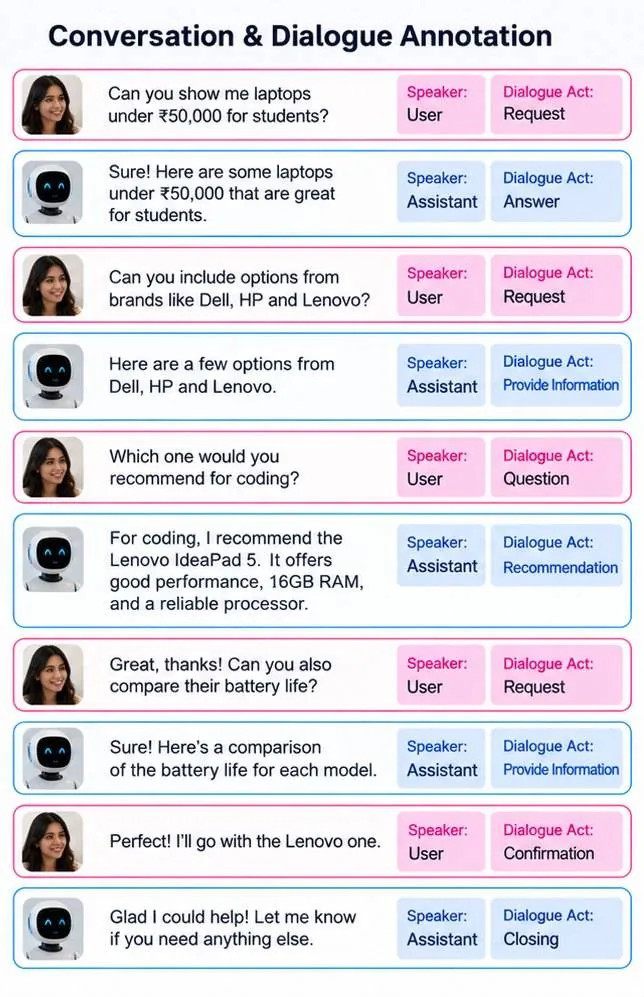
What we annotate
Common task types. Every project follows guidelines agreed with you at scoping.
Output rating & review
Scoring model answers for accuracy, helpfulness, and safety.
Preference ranking
Comparing responses side by side to show which is better and why.
Prompt & response writing
Creating example prompts and reference answers for training.
Error & failure analysis
Finding and categorising where a model goes wrong.
Benchmark & test sets
Curated evaluation sets, including rare and edge cases.
Safety & policy review
Checking outputs against your content and safety guidelines.
Used across industries
Where this service is most often applied.
AI Needs More Than Data.
Talk to our team about annotation programs, datasets, and enterprise AI infrastructure tailored to your domain.